
Dolphin: Moving Towards Closed-loop Auto-research through Thinking, Practice, and Feedback
Dolphin closes the research loop that The AI Scientist left open - feeding experimental outcomes back into idea generation so that idea quality improves across cycles - and, evaluated on standard benchmarks rather than toy templates, produces methods comparable to state-of-the-art on tasks such as 3D point-cloud classification.
2025 · Paper
1. Motivation
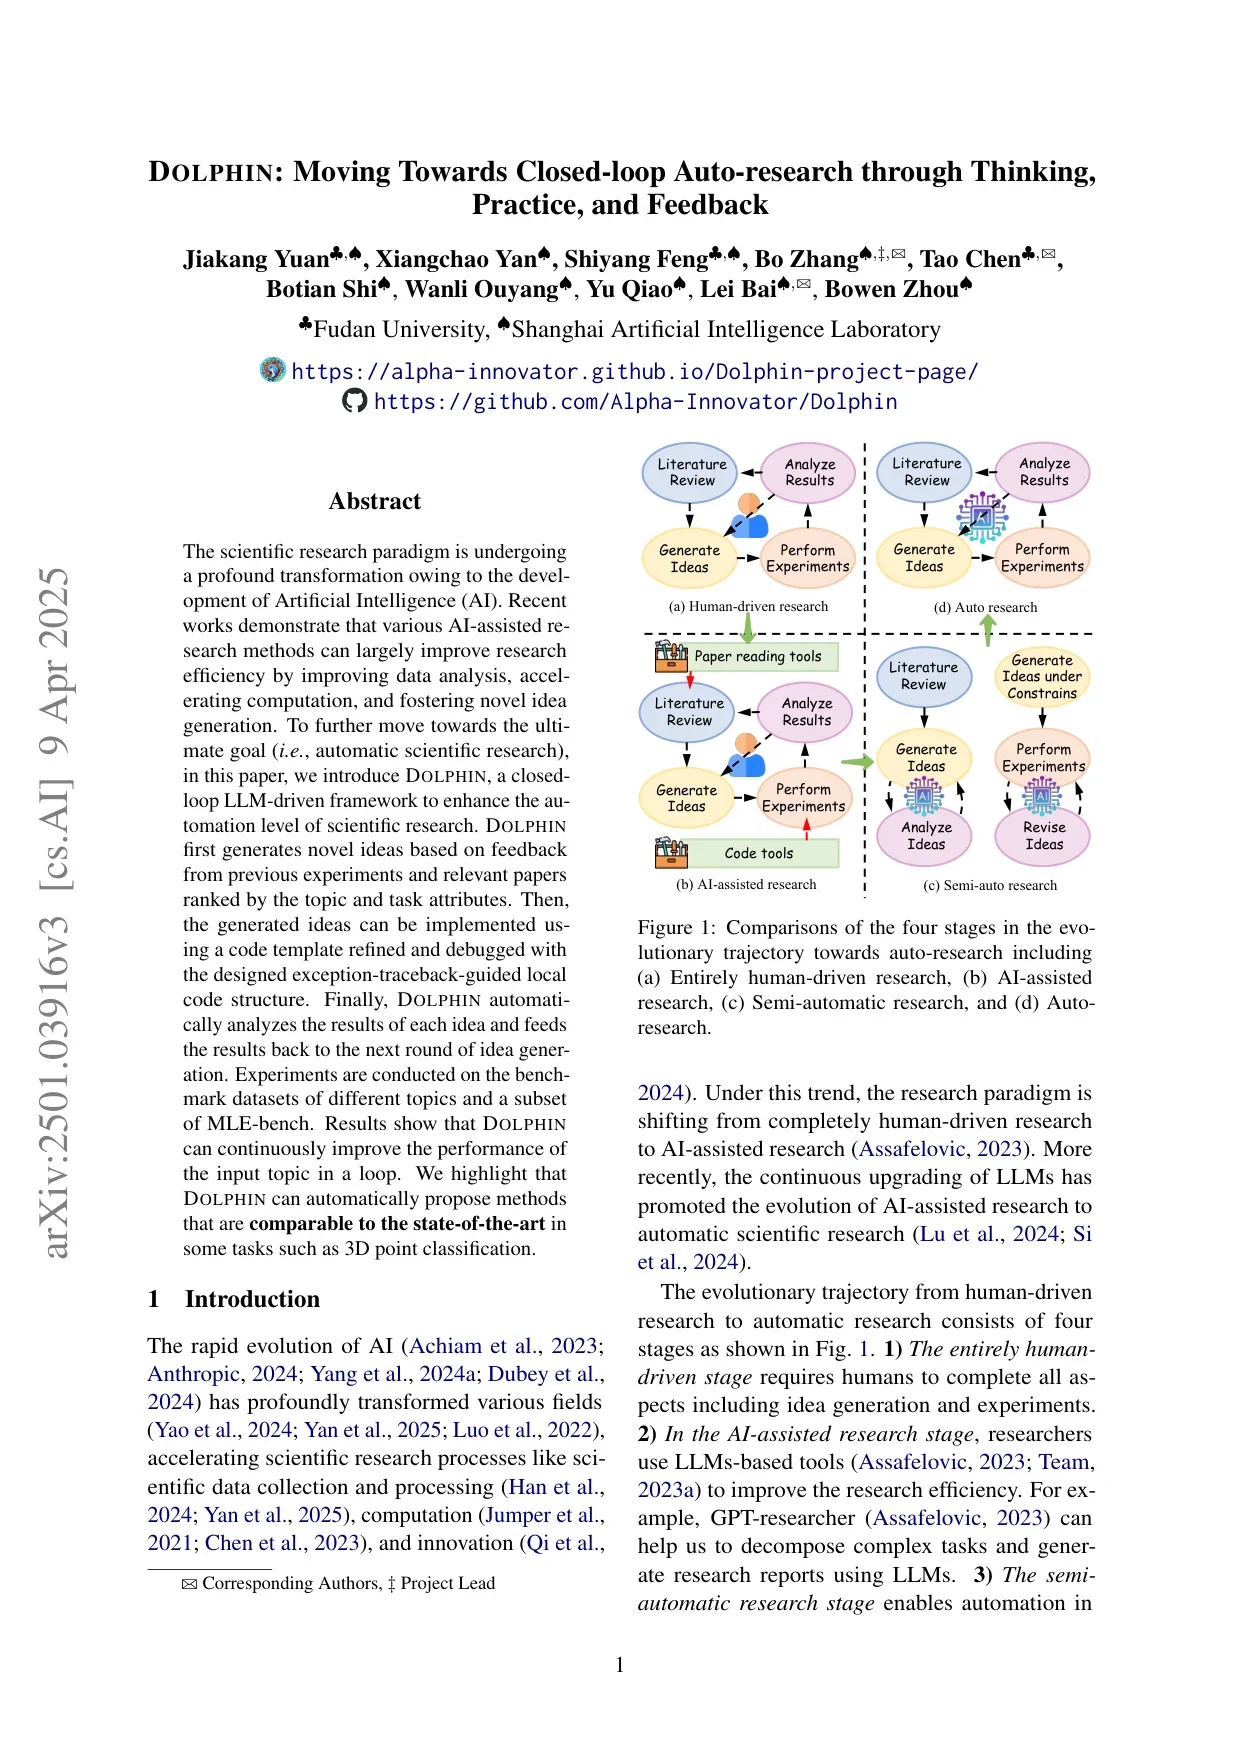
The AI Scientist (v1) demonstrated end-to-end paper generation but has two structural gaps: it evaluates on “self-constructed simple datasets, making it challenging to draw meaningful comparisons with existing methods,” and its ideas are never improved by experimental outcomes - each idea is generated blind to what worked before.12 Dolphin’s claim is that research is fundamentally iterative: real scientists refine hypotheses after seeing results. The gap closed is the feedback edge from experiment outcomes back into ideation, plus evaluation on standard benchmarks (CIFAR-100, ModelNet40, SST-2, and a subset of MLE-bench) that permits direct comparison with human-designed methods.1
2. Methodology
2.1 Search Structure
Dolphin is a sequential closed loop, not a tree: idea generation → experimental verification → results feedback, repeated over a research topic (e.g., 3D classification on ModelNet40). In the main experiments, 20 ideas are generated per loop and 2 loops are run per task (40 ideas total); a separate loop analysis extends to 3 loops. The feedback edge is the paper’s defining feature: loop ‘s generation prompt is conditioned on loop ‘s measured outcomes, so the search distribution shifts toward idea categories that empirically worked.1
2.2 State Representation
The research state has three components. (1) A retrieved reference set: 50 papers pulled via the Semantic Scholar API, each LLM-scored 1–10 on topic relevance plus alignment of model inputs/outputs/metrics with the task; only papers scoring >8 are kept. (2) An idea bank : sentence embeddings (sentence-transformer/all-roberta-large-v1) of summaries of all prior ideas. (3) Performance outcomes of executed ideas, each classified as improvement / maintenance / decline relative to the reference code’s performance.1
2.3 Generation Mechanism
Ideas (title + experiment plan + summary) are generated by GPT-4o (gpt-4o-2024-08-06), conditioned on the ranked references and - from loop 2 onward - feedback describing which prior ideas improved, maintained, or degraded performance. Code is then generated by deepseek-v2.5 (via Ollama) using the aider framework, following The AI Scientist’s practice of self-reflection to remove syntax errors before execution, on top of a fixed per-topic reference codebase.13
2.4 Evaluation & Grounding
Ground truth is real benchmark performance on standard datasets - CIFAR-100, ModelNet40, SST-2, and (in v3) an MLE-bench subset - an explicit contrast with AI Scientist v1’s toy templates. Improvement is measured against the authors’ reimplemented baselines (marked Baselines†), not quoted literature numbers, which matters for interpreting the headline claims (Section 4).1
2.5 Memory / Information Flow
The idea bank is the cross-loop cumulative memory: initialized empty, seeded after loop 1 with embeddings of ineffective ideas (so the generator avoids them), and augmented with embeddings of performance-maintaining/improving ideas, whose summaries are injected into the next-loop generation prompt. Results are classified per idea before being written back, so memory stores evaluated experience, not raw text.1
2.6 Selection & Propagation
Two filters gate which of the 20 generated ideas reach the experiment stage: (1) independence - cosine similarity of the idea-summary embedding against , discarding any idea with max similarity > 0.8; (2) novelty - an LLM judges the idea against Semantic Scholar–retrieved papers (“Following AI-Scientist”). Only novel and independent ideas are verified experimentally, with a maximum of 5 debugging iterations per idea.1
2.7 Anti-Slop / Anti-Hallucination Mechanisms
The strongest control is exception-traceback-guided debugging: when execution fails, the system extracts the function name, line number, and code from the Python traceback - restricted to custom code, excluding library calls - has the LLM reconstruct the local code structure, and then edits. This raised execution success from 33.3% to 50.0% in one analysis, and an ablation shows local-code-structure + traceback beats traceback alone and neither (e.g., 7/15 successful executions vs 4/15 baseline in loop 1).1 The feedback loop itself acts as a redundancy filter. Residual slop channel: novelty is still LLM-self-judged against retrieved papers - plausible but unverified ground truth.1
3. Results
- ModelNet40 (3D classification): PointNet baseline 91.0% overall accuracy (OA) / 87.6% mean class accuracy (authors’ reimplementation); Dolphin’s best idea (“PointNet-CSR”) reached 93.9% OA / 91.1% mAcc, comparable to the human-designed state-of-the-art GPSFormer (93.8 / 91.8); average improvement +1.0 OA; 5/40 ideas improved.1
- CIFAR-100: WRN-28-10 baseline 81.2%; Dolphin max 82.0% vs human-designed ResNeXt 82.2%; 6/40 ideas improved. SST-2: BERT-base 91.0%; Dolphin max 92.5% vs BERT-large 93.1%; 6/40 ideas.1
- Feedback effect: improvement rate rises across loops - 2/7 in loop 1, 3/6 in loop 2, 4/8 in loop 3 (9/21 total) in the loop analysis - while average cost per idea grows from ≈$0.184 to ≈$0.218 as feedback accumulates.1
- MLE-bench (v3): Dolphin wraps other code frameworks; on an AIDE-generated template it lifted insult-detection 81.0 → 84.7 (“gold medal level”), tabular playground 95.3 → 96.2, and jigsaw toxic-comment 94.7 → 97.2.3
- Note: baselines are author reimplementations (no pretraining/voting), not re-runs of published checkpoints.1
4. Limitations & Assumptions
Dolphin requires a fixed per-topic reference codebase and benchmark - it is not template-free like AI Scientist-v2. Per-idea success is modest (≈5–6 of 40 ideas beat baseline per task), and only 2 loops per task are run in the main table. The novelty filter is LLM-self-judged; “comparable to SOTA” rests on reimplemented baselines; Transformer-based 2D methods (ViT) are excluded “due to their heavy dependence on pre-training.” The authors state future work needs code models that can modify project-level code and multi-disciplinary retrieval. No statistical significance is reported.13
5. Critical Analysis
- Distinctive strength: It is the only system in this theme with a quantified, measured feedback loop - the 2/7 → 4/8 improvement-rate trend and the 33.3% → 50.0% execution-success gain from traceback-guided debugging are rare pieces of direct evidence that a memory/feedback mechanism and an anti-slop mechanism actually work, rather than being asserted.
- Structural weakness / trade-off: The loop is shallow (2 loops) and the search is flat - there is no tree or population, so exploration depth per idea is capped at 5 debugging rounds; evaluation scope (3 modest-scale tasks) is far narrower than the “open-ended” framing of its predecessor.
- Connections: Dolphin explicitly inherits The AI Scientist v1’s (arXiv:2408.06292) Semantic Scholar novelty check, aider-based self-reflection, and code workflow, while criticizing its toy datasets and missing feedback edge.2 Its v3 integrates AIDE and Agent Laboratory (arXiv:2501.04227) code templates on MLE-bench, positioning it as a feedback wrapper around the same MLE-agent ecosystem that AI Scientist-v2 (arXiv:2504.08066) draws its tree search from.34 Its idea bank attacks the same cumulative-memory problem as AgentRxiv (arXiv:2503.18102), which solves it with a shared preprint server instead of embeddings.5
6. References
- [Yuan et al., 2025] “Dolphin: Moving Towards Closed-loop Auto-research through Thinking, Practice, and Feedback” - https://arxiv.org/pdf/2501.03916 (abs: https://arxiv.org/abs/2501.03916; v3 HTML: https://arxiv.org/html/2501.03916v3)
- [Yuan et al., 2025] “Dolphin code repository” - https://github.com/Alpha-Innovator/Dolphin
- [Lu et al., 2024] “The AI Scientist: Towards Fully Automated Open-Ended Scientific Discovery” - https://arxiv.org/pdf/2408.06292
- [Yamada et al., 2025] “The AI Scientist-v2: Workshop-Level Automated Scientific Discovery via Agentic Tree Search” - https://arxiv.org/pdf/2504.08066
- [Schmidgall et al., 2025] “Agent Laboratory: Using LLM Agents as Research Assistants” - https://arxiv.org/pdf/2501.04227
- [Schmidgall & Moor, 2025] “AgentRxiv: Towards Collaborative Autonomous Research” - https://arxiv.org/pdf/2503.18102
Footnotes
-
Dolphin v1 PDF, arXiv:2501.03916 - https://arxiv.org/pdf/2501.03916 ↩ ↩2 ↩3 ↩4 ↩5 ↩6 ↩7 ↩8 ↩9 ↩10 ↩11 ↩12 ↩13 ↩14 ↩15
-
AI Scientist v1 PDF - https://arxiv.org/pdf/2408.06292 ↩ ↩2
-
Dolphin v3 HTML - https://arxiv.org/html/2501.03916v3 ↩ ↩2 ↩3 ↩4
-
AI Scientist-v2 PDF - https://arxiv.org/pdf/2504.08066 ↩
-
AgentRxiv PDF - https://arxiv.org/pdf/2503.18102 ↩